AI document processing: supplier documents into clean data
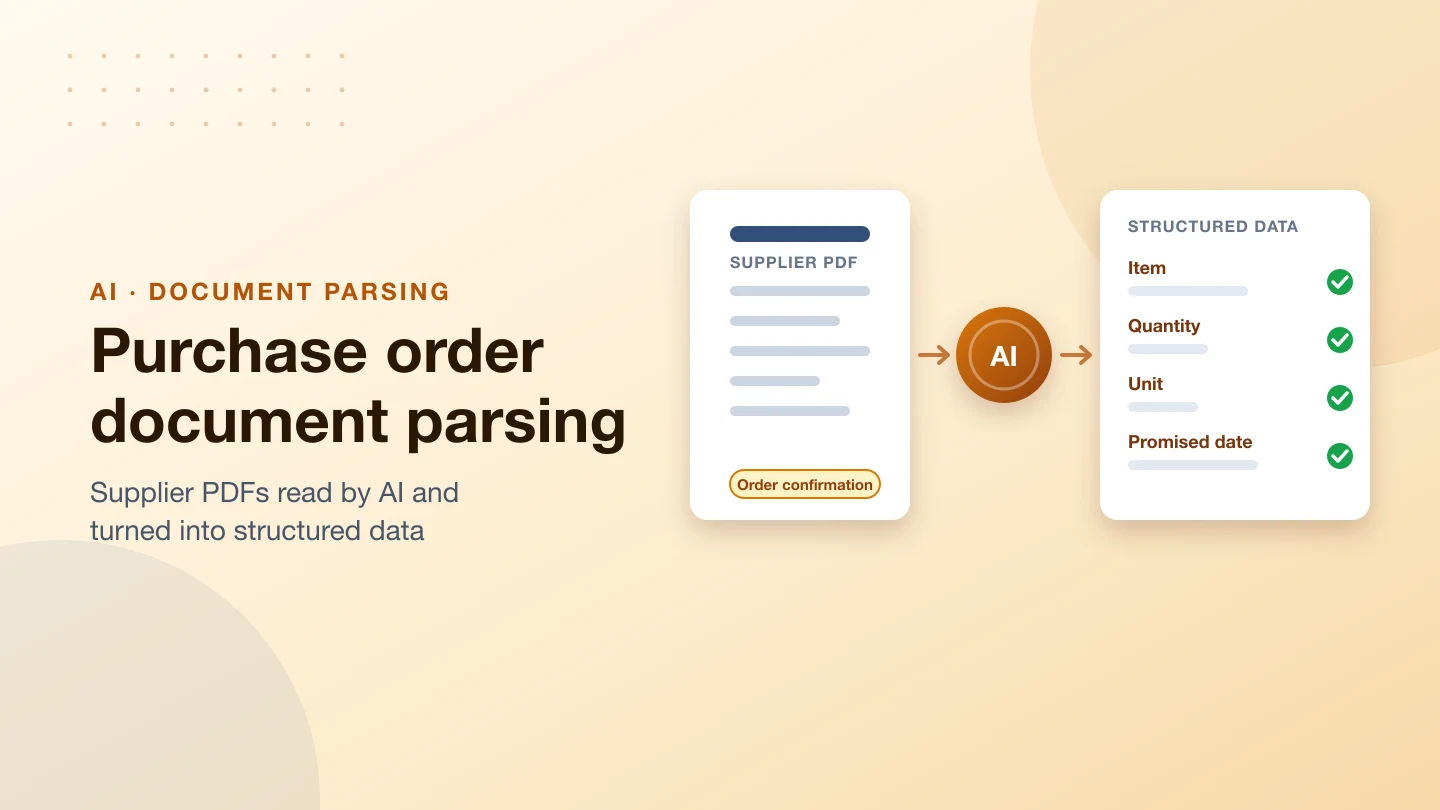
A pipeline that reads purchase order acknowledgments, invoices and order confirmations and turns them into structured data your systems can use. It runs live for an ecommerce distribution team, with one schema per supplier and checks for the errors that slip through.
Price on request. We host it, or install it in your own cloud account.
- One schema and parser per supplier or customer account
- Text or vision models, chosen per supplier after testing
- Checks for wrong units, promised dates and amounts
- Hosted by us, or installed in your own cloud account
Who it is for
Teams that retype or check documents from many senders, each in its own layout:
- Distributors and retailers receiving order acknowledgments from suppliers.
- Finance teams processing supplier invoices.
- Operations teams matching order confirmations against what was ordered.
When you need something more
If the extracted data has to drive decisions, approvals or actions in other systems, we extend the pipeline into a workflow. See workflow automation and AI agents.
What is included
A schema per sender
Each supplier and customer account gets its own JSON schema and parser, because one parser for every layout makes more mistakes.Text or vision models
We test text-based and vision-based extraction for each supplier and use whichever reads its documents more accurately.Error checks
Checks for the mistakes that pass a format test: unit-of-measure mismatches, promised dates, quantities and amounts.Ongoing tuning
Suppliers change their documents. We keep tuning parsers for accuracy and efficiency as they do.Data your systems can use
Clean, structured records delivered to your systems, ready to match against the orders you placed.Support notes
Handover and support notes so your team knows how a parsing error is found and fixed.How it works
How a document becomes clean data
Simplified diagram. The models and where the data goes are chosen for your setup.
- A supplier or customer document arrives: a PDF, a Word file, a scan, or a ZIP of several files.
- The pipeline opens archives and reads each file: the text of PDF and Word files, or images of the pages for a vision model.
- It uses the schema for that sender: the fields to fill, set up once for each supplier or customer account.
- A text or vision model, chosen per sender after testing, fills the fields. Checks then catch mistakes that pass a format test: wrong units, promised dates, quantities and amounts.
- The structured data goes to your system by webhook or into a database. When a sender changes its layout, we tune its parser.
How setup works
- Demo call. We look at a sample of your documents and where the data needs to go.
- Schemas. We define the fields for each sender.
- Testing. We compare text and vision models on real documents and pick one per sender.
- Connection. The structured data goes to your system.
- Tuning. We watch the errors and fix parsers as suppliers change their documents.
Hosting, ownership and price
- We host it and keep the parsers tuned for a monthly fee.
- We install it in your own cloud account, so the documents and data stay with you.
Price is on request: it depends on the number of senders, document volume and where the data goes.
Where it runs today
- Document parsing pipeline for purchase order acknowledgments: supplier documents for an ecommerce distribution team turned into structured data, one schema per supplier, with ongoing error fixing.
- AI parsing of uploaded documents on AWS Lambda: a file uploaded to S3 is unzipped or its text extracted from PDF or Word, sent to the ChatGPT API, stored as JSON and announced to the website by webhook.
Frequently asked questions
Which documents can it read?
Purchase order acknowledgments, invoices, order confirmations and similar documents, as PDFs or scans. Each sender's layout gets its own schema.
How accurate is it?
Accuracy is measured per sender on your own documents during testing. Errors that pass a format check, such as a wrong unit of measure or promised date, get their own checks, and we keep tuning as layouts change.
Do we need to change how suppliers send documents?
No. The pipeline reads what they already send.
Where are our documents processed?
With the hosted option, in our cloud account; with the install option, in yours. We tell you which model providers process the documents and on what terms.
How much does it cost?
Price is on request, based on the number of senders, document volume and the systems the data goes to. Book a demo call and we will quote.
Send us a few sample documents
Book a demo call. We show the pipeline and talk through what your documents would need.
Book a demo or ask a question
Tell us about your business and what you want the solution to do. We reply with questions and a time for a demo call.